 Meta
 GoogleAvailable
Model
Gemini 4 Neon
Google's new Gemini 4 model pairs a 1M-token context window and four thinking levels with lower cost per task. It scores 61 on the AA Intelligence Index and targets complex coding, analysis, and cyber workflows.
Loading launches from 4 labs
Topic
Speech in or out, transcription, music and sound
GoogleAvailableGoogle's new Gemini 4 model pairs a 1M-token context window and four thinking levels with lower cost per task. It scores 61 on the AA Intelligence Index and targets complex coding, analysis, and cyber workflows.
 GoogleAvailable
Google rolled out Genie 4 to AI Ultra subscribers, featuring real-time natural language environment editing, native adaptive audio, and interactive world generation.
GoogleAvailableGoogle added voice-driven editing, rewriting, and formatting to gemini-3.5-transcribe and gemini-3.5-transcribe-live, letting users modify dictated speech or existing text by voice.
 GoogleAvailable
Google is rolling out 66 regional voices on Android and iOS, adding localized accents and speech patterns to Gemini voice interactions.
 GoogleAvailable
Google has integrated its Gemini 4 Hydrogen model into Google Search globally, improving intent understanding, query fan-out for better web linking, visual responses, and multilingual support.
 GoogleAvailable
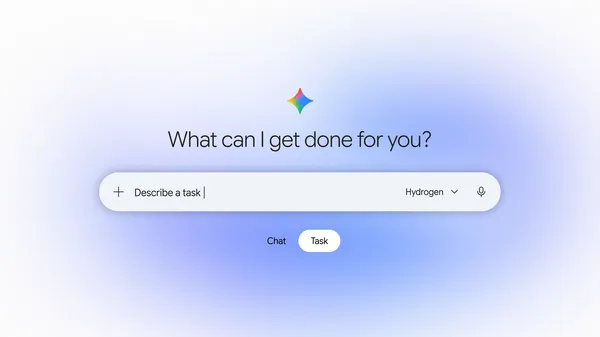
Google's new Gemini 4 Hydrogen model features a 1M-token unified context window, four thinking levels, and long decode for agentic workflows.
 GoogleAvailable
Google introduced the Gemini Decisions API powered by the Gemini Decision 1 model, enabling developers to evaluate up to 1,000 yes/no, choice, and rubric-scoring questions in a single multimodal pass.
 GoogleAvailable
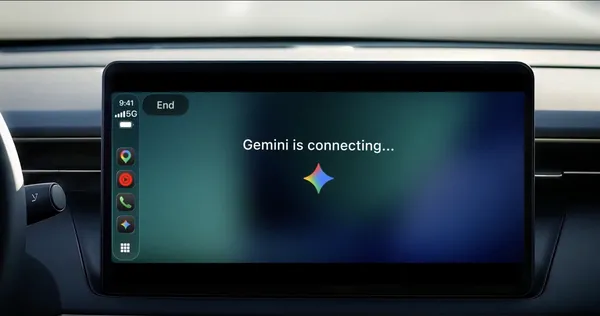
Google is bringing the Gemini app with Gemini Live to Apple CarPlay, enabling hands-free natural conversations, calendar management, and email summaries while driving.
 GoogleAvailable
Gemini can now control, change, or fix device settings and storage by voice. Rolling out on Pixel 10 series and Motorola Signature 27.
GoogleAvailableGoogle rolls out Gemini Intelligence to motorola signature 27 (U.S. pre-order Nov 19) and Pixel 10 series via Pixel Drop, adding Rambler voice-to-text and task automation in UK, India, Japan.
GoogleAvailableGemini API function responses now support Office/OpenDocument files, audio, video, and file URIs, letting tools return richer data to the model.
GoogleAvailableThe Gemini API now accepts PowerPoint (PPT), OpenDocument Presentation (ODP), and OpenDocument Spreadsheet (ODS) files as input, plus page-image processing for Word (DOC) files.
GoogleBetaGoogle released voice remixing for Gemini 3.8 TTS, allowing developers to modify existing voices using text prompts to create new stored voice IDs.
 GoogleAvailable
Google released EmbeddingGemma 2, a 740M-parameter open embedding model on the Gemma 4 architecture. It maps code, images, video, and audio into one unified space on edge devices for private, offline multimodal search.
GoogleAvailableGoogle is expanding SynthID Detector globally in English to help users verify whether images, videos, or audio clips were generated by AI.
 GoogleAvailable
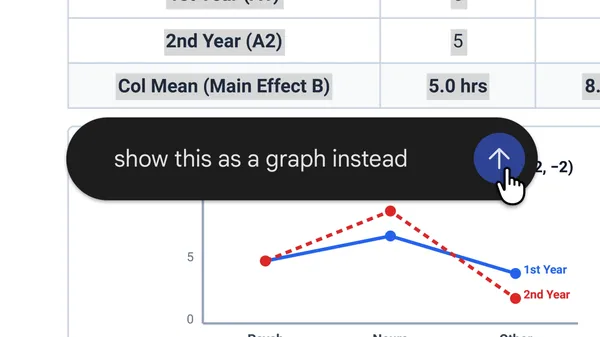
Gemini users can now preview, manually edit, and instruct AI to refine documents, spreadsheets, PDFs, and code directly inside the chat interface.
 GoogleAvailable
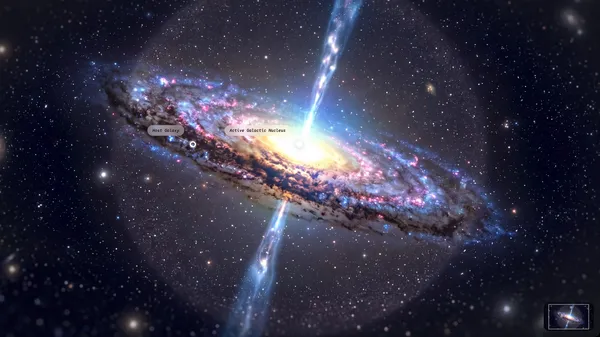
Google launched visual, interactive explorations in the Gemini app for studying complex science and history topics layer-by-layer.
 GoogleAvailable
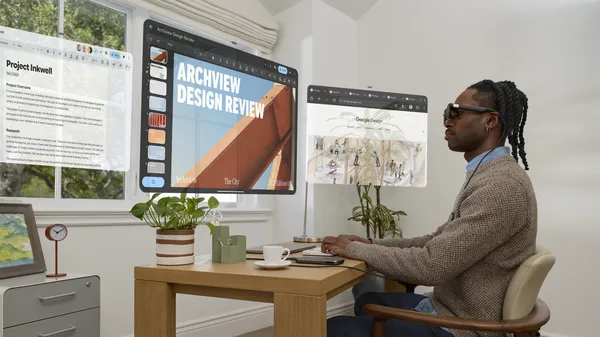
XREAL AURA is a pair of tethered XR glasses running Android XR. It projects apps onto a transparent 70-degree field of view and uses Gemini to analyze your screens and physical surroundings.
 GooglePreview
Genie 4 is a real-time world model that generates interactive simulations with native audio and physics. It helps build safe training environments for AI agents and robots.
GoogleAvailableGoogle launched Gemini 4 Argon globally, a frontier reasoning model built for complex coding, financial analysis, legal tasks, and robotics.
 GoogleAvailable
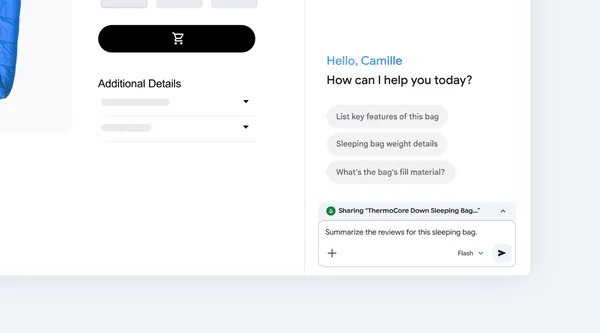
Google added Gemini to the Chrome side panel so users can get quick answers on any website. It summarizes articles, compares products, and explains complex topics directly in the browser.
 GoogleOn request
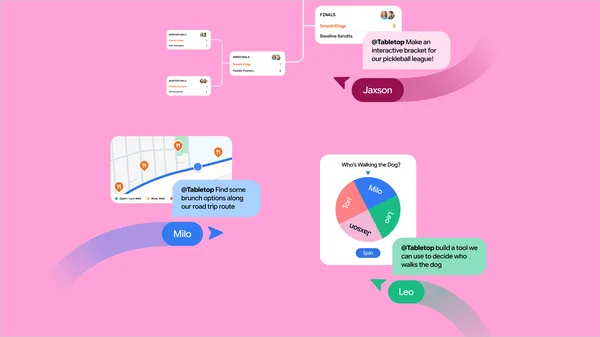
Tabletop is a Google Labs experiment for real-time group collaboration, allowing users to generate custom interactive itineraries, polls, and tools using AI prompts.
 GoogleAvailable
Google and Artificial Analysis released MKA, a benchmark evaluating how AI agents perform multi-step, visually complex tasks across 10 professional verticals.